A Node.js heap mystery
I encountered another production mystery - a Node.js app was consuming 665 MiB of memory. I didn’t know where it was coming from, so I started by looking at process.memoryUsage():
{
  "rss": 697303040,
  "heapTotal": 135147520,
  "heapUsed": 126842024,
  "external": 25004037,
  "arrayBuffers": 33762595
}
heapTotal was only 129 MiB (!). heapUsed is included in heapTotal, so even if we add arrayBuffers, V8 was seeing 161.09 MiB. Not even close to those 665 MiB from RSS. So where is the rest?
I ended up reading /proc/pid/smaps and found 1461 anonymous mappings of exactly 256 KiB, which is the size of a V8 heap page.
256KB 1e20080000-1e200c0000 rw-p 00000000 00:00 0
256KB 2efb440000-2efb480000 rw-p 00000000 00:00 0
So here are the facts gathered so far: RSS is much bigger than what V8’s internal metrics can account for, and smaps shows a bunch of anonymous pages that nobody seems to know about.
I forced a HeapProfiler.collectGarbage through the V8 inspector, and RSS dropped by around 230 MiB.
Now we are going somewhere. The process RSS dropped from 665 MiB to 435 MiB.
Ok, so maybe we had a bunch of unused pages, and the GC released them? I don’t think so. The difference between total and used is only 135147520 - 126842024 = 7 MiB. Which makes explaining the 230 MiB even harder.
Where did those 230 MiB come from? One thing I didn’t do, and I’ll regret it for a long time, was counting the anonymous mappings after the collection, so I’ll never know if the count was different - I’m betting it was.
In any case, one question remained at this point: if collectGarbage dropped 230 MiB, what was happening to that process? The garbage collector wasn’t running at all? Because RSS spiked, and never dropped.
Well, I investigated (a lot), and the bottom line is: the collector I ran is not the same collector V8 normally runs. V8’s garbage collector returns pages to the pool, which may still count towards RSS. The reason for that is simple: if pages are in the pool, V8 doesn’t need to ask the OS every time it needs a new page. Fewer syscalls. The garbage collection I ran bypassed that and collected things that were in the pool as well.
To bring the math back: we had 1461 pages of 256 KiB, which is 365 MiB. At most, 129 MiB of that could belong to heapTotal. That leaves about 236 MiB, and the GC reclaimed about 230. That explains the math I was fighting with. Now I can go back to sleep.
Or maybe not: how I discovered the difference between the GCs, for enthusiasts
I searched. And I found a promising PR. But from 2018.
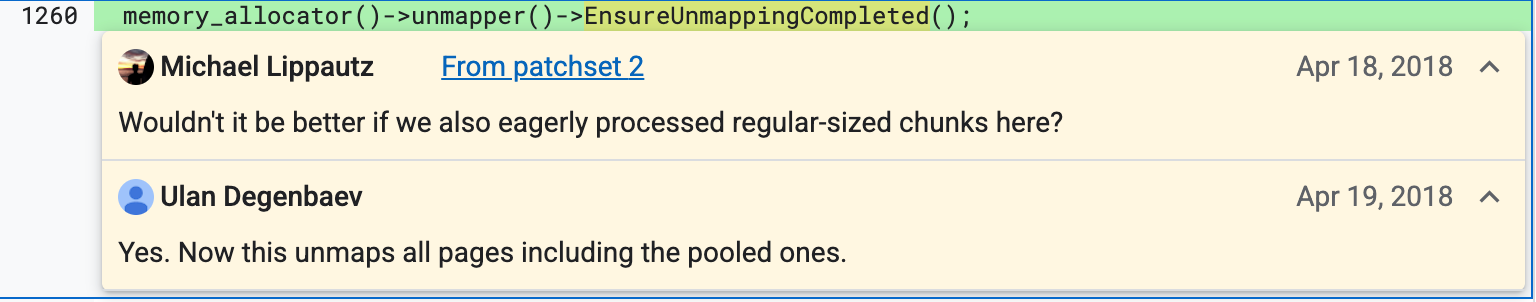
This is a change in CollectAllAvailableGarbage from heap/heap.cc, and it explains what happened. I checked if that change survived recent versions. And… nope. It didn’t.
Then I found the commit that changed it. In January 2024, Anton Bikineev introduced a page pool in V8. The commit message says: “The CL replaces the current way of handling free pages - concurrent unmapper - with a page pool. The latter is very similar to what Oilpan already uses. The pages are kept alive until a memory-reducing GC kicks in, after which they get released.”
Ok. To make sense of all of this: collectGarbage does not follow the same rules. Regular GCs put empty pages into the pool. Those pages leave heapTotal, but RSS still counts them. Only a “memory-reducing” GC returns the pool to the OS. The HeapProfiler.collectGarbage I used calls LowMemoryNotification, which runs that kind of GC.
Note: if you ever need to do something like this, you can send SIGUSR1 to a running process to activate the V8 inspector. I used nsenter -t pid -n to enter the container network namespace. curl http://127.0.0.1:9229/json/list returns the websocket URL of the inspector, and through that websocket we can have a lot of fun sending CDP commands. The inspector stays open until the process restarts, so make sure you restart the pod when you are done. Here is the list of everything you can do while interacting with the inspector: https://chromedevtools.github.io/devtools-protocol/v8/
This post was drastically updated in September 2026.